Understanding how Mogothrow77 software is built requires looking at the intersection of modular design and accessible deployment workflows. Users often wonder how these systems are structured to handle complex data tasks while remaining manageable for individual developers.
This analysis covers the foundational architecture, the management of source code, and the essential steps for a successful installation on your local system. By examining these technical layers, you will gain a clearer picture of the development philosophy driving the project and how you can effectively integrate it into your own workflow.
Defining the Core Architecture
At its heart, the software relies on a decoupled design that separates the front-end interface from the back-end processing service. This modular approach ensures that each component can be updated or debugged independently without disrupting the entire system. Developers refer to this as a service-oriented architecture, which is highly preferred for modern, scalable applications.
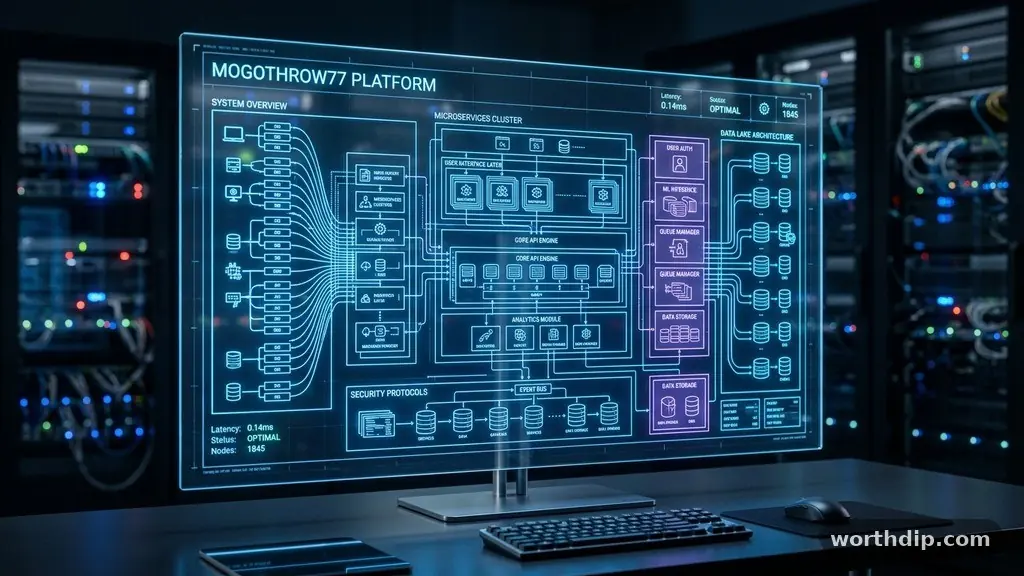
The structural blueprint of the project is often represented by a high-level diagram that maps the flow of data from the user input to the database. By maintaining this separation, the creators allow the software to handle multiple concurrent tasks without bottlenecks. This design choice is fundamental to the stability of the platform, even when it is processing large batches of information.
When you look at the system, you will notice that the logic is partitioned into distinct layers. Each layer has a specific set of responsibilities, such as authentication, data validation, or external API communication. This layering prevents the code from becoming monolithic, which is a common problem in older software development models.
Managing the Source Code
The source code for this project is maintained in a version-controlled environment that tracks every change made to the application. Using a centralized repository allows for transparency, as users can inspect the history of the project to see how specific features were implemented over time. This level of openness is a standard expectation in modern open-source development.
Developers working on the code follow a strict set of branch policies to ensure that only tested features are merged into the main release. If you are interested in contributing, you would typically fork the repository and work on your own local version before submitting a request to merge your changes. This process keeps the master branch clean and functional for all users.
Documentation is another critical aspect of how the source is managed. Detailed comments within the code files help developers understand the intent behind complex algorithms. You can find more information about these standard practices through ISO software engineering standards, which provide a framework for professional documentation and quality control.
Essential Requirements for Installation
Before you begin the installation, you must ensure your machine meets the minimum hardware and software specifications. The software requires a specific runtime environment, often involving a language interpreter or a virtual machine to execute the source code. Failing to meet these requirements can lead to errors during the setup phase.
Most installations follow a standard sequence of tasks designed to minimize user effort. You will typically start by cloning the repository, followed by the installation of necessary dependencies via a package manager. These managers automatically fetch the libraries needed for the application to function, ensuring that your environment matches that of the original developers.
The following table outlines the typical hardware and software profile required for a smooth installation:
| Category | Minimum Requirement | Recommended |
|---|---|---|
| Processor | Dual-core 2.0GHz | Quad-core 3.0GHz+ |
| RAM | 4GB | 8GB or more |
| Disk Space | 500MB | 2GB (for logs/data) |
| OS | Linux/Windows/macOS | Linux (Ubuntu 22.04+) |
Automated Deployment Workflows
Automation plays a massive role in how this software is built and maintained. By using continuous integration tools, the developers can automatically run tests every time a new piece of code is pushed to the repository. This ensures that a new feature does not accidentally break existing functionality elsewhere in the system.
These automated pipelines are configured to perform several key tasks during the build process. They compile the source code, run unit tests, and generate the final executable files that users download. This approach significantly reduces human error and ensures that every release is consistent in quality.
For the end user, this means that the installation packages are generally reliable. When you run the setup script, you are essentially triggering a series of pre-defined commands that configure your local environment to match the requirements of the software. This consistency is one of the primary benefits of modern automated development cycles.
Handling Data and Persistence
The way the system handles data is a crucial part of its architecture. Most instances of this software use a relational database to store user settings, logs, and other persistent information. This ensures that your data remains intact even if the application is restarted or the server is rebooted.
The schema of the database is designed to be flexible, allowing for future expansion without requiring a complete rewrite of the application. Developers often use migration scripts to update the database structure as new versions of the software are released. These scripts automate the process of adding new tables or modifying existing fields.
When you install the software, you are usually prompted to configure your database connection. This step is vital, as it allows the application to communicate with the storage layer. Proper configuration here prevents data corruption and ensures that the application can read and write information at the necessary speeds.
Scalability and Performance Tuning
Although the software is built to be lightweight, it is designed with scalability in mind. If you find that your installation needs to handle more load, you can adjust the service settings to allocate more resources to the application. This is a common requirement for enterprise environments that need to manage high volumes of concurrent requests.
Performance tuning often involves optimizing the way the application interacts with the underlying hardware. You might adjust the cache settings or modify the connection pooling to improve response times. These adjustments are usually documented in the configuration files, allowing administrators to fine-tune the system for their specific use case.
Monitoring tools are also integrated into the architecture to help you track performance metrics. These tools provide real-time data on CPU usage, memory consumption, and request latency. Having access to this information is essential for troubleshooting and ensures that the software continues to perform well under varying workloads.
Common Development Milestones
The evolution of the project can be traced through several major development milestones. These milestones often mark the release of significant features or the transition to a more efficient architecture. Tracking these events helps users understand the maturity of the software and its long-term direction.
- Initial release of the core engine and base libraries.
- Transition to a modular service-based architecture for better scalability.
- Introduction of automated testing pipelines to improve code reliability.
- Implementation of a new API layer for improved third-party integrations.
- Launch of a comprehensive documentation portal for developers and users.
Each of these steps represents a concerted effort to improve the software’s usability and technical depth. By focusing on these milestones, the development team has created a system that is both feature-rich and maintainable. This history of steady growth is a positive indicator for anyone considering long-term adoption of the platform.
Security and Access Control
Security is integrated into the architecture from the ground up, rather than being an afterthought. The system uses robust authentication protocols to ensure that only authorized users can access sensitive functions. This is particularly important in enterprise settings where data privacy is a top priority.
Access control lists are used to define the permissions for different user roles within the software. You can configure these settings to restrict access to specific services or datasets, providing a granular level of control over the system. This design ensures that even if one component is compromised, the broader system remains secure.
Regular security audits are performed on the source code to identify and patch potential vulnerabilities. This proactive approach helps protect users against emerging threats. When you install the software, it is recommended that you follow the security guidelines provided in the documentation to ensure your local instance is properly hardened.
FAQ
What is the primary language used in the software?
The software is primarily written in languages that support high-concurrency and modular design, often utilizing standard industry frameworks to ensure performance and maintainability across different operating systems.
Do I need to be a developer to install it?
You do not need to be a professional developer, but basic familiarity with command-line interfaces and local environment configuration is highly recommended for a successful installation and setup process.
How often are updates released?
Updates are released on a regular schedule determined by the development roadmap, usually focusing on security patches, performance improvements, and new feature additions to the existing modular services.
Can I customize the source code?
Yes, since the source code is accessible, you can modify it to suit your specific needs; however, it is advised that you maintain your own branch to avoid conflicts with future official updates.
Where can I find the official documentation?
The official documentation is typically hosted alongside the source code repository or on a dedicated project website, providing detailed guides on architecture, configuration, and troubleshooting for all users.
Conclusion
Building a deep understanding of how Mogothrow77 software is built provides a significant advantage when you begin the installation and configuration process. By recognizing the modular architecture and the disciplined approach to source code management, you can better navigate the system’s features and ensure it meets your specific requirements. Whether you are deploying it for personal use or as part of a larger enterprise system, the key is to follow the established documentation and maintain a clean environment.
As you continue to explore the capabilities of this software, remember that the community and the available resources are there to support your development journey. Engaging with the project and contributing your own insights will only help improve the ecosystem for everyone involved.